2026
When KV Meets Embeddings: Dynamic GPU Memory Allocation for Accelerating Generative Recommender Serving
Wenjun Yu, Amelie Chi Zhou, Shuguang Han — Alibaba (XianYu)
(SC 2026, CCF-A (19.2%)) International Conference for High Performance Computing, Networking, Storage, and Analysis
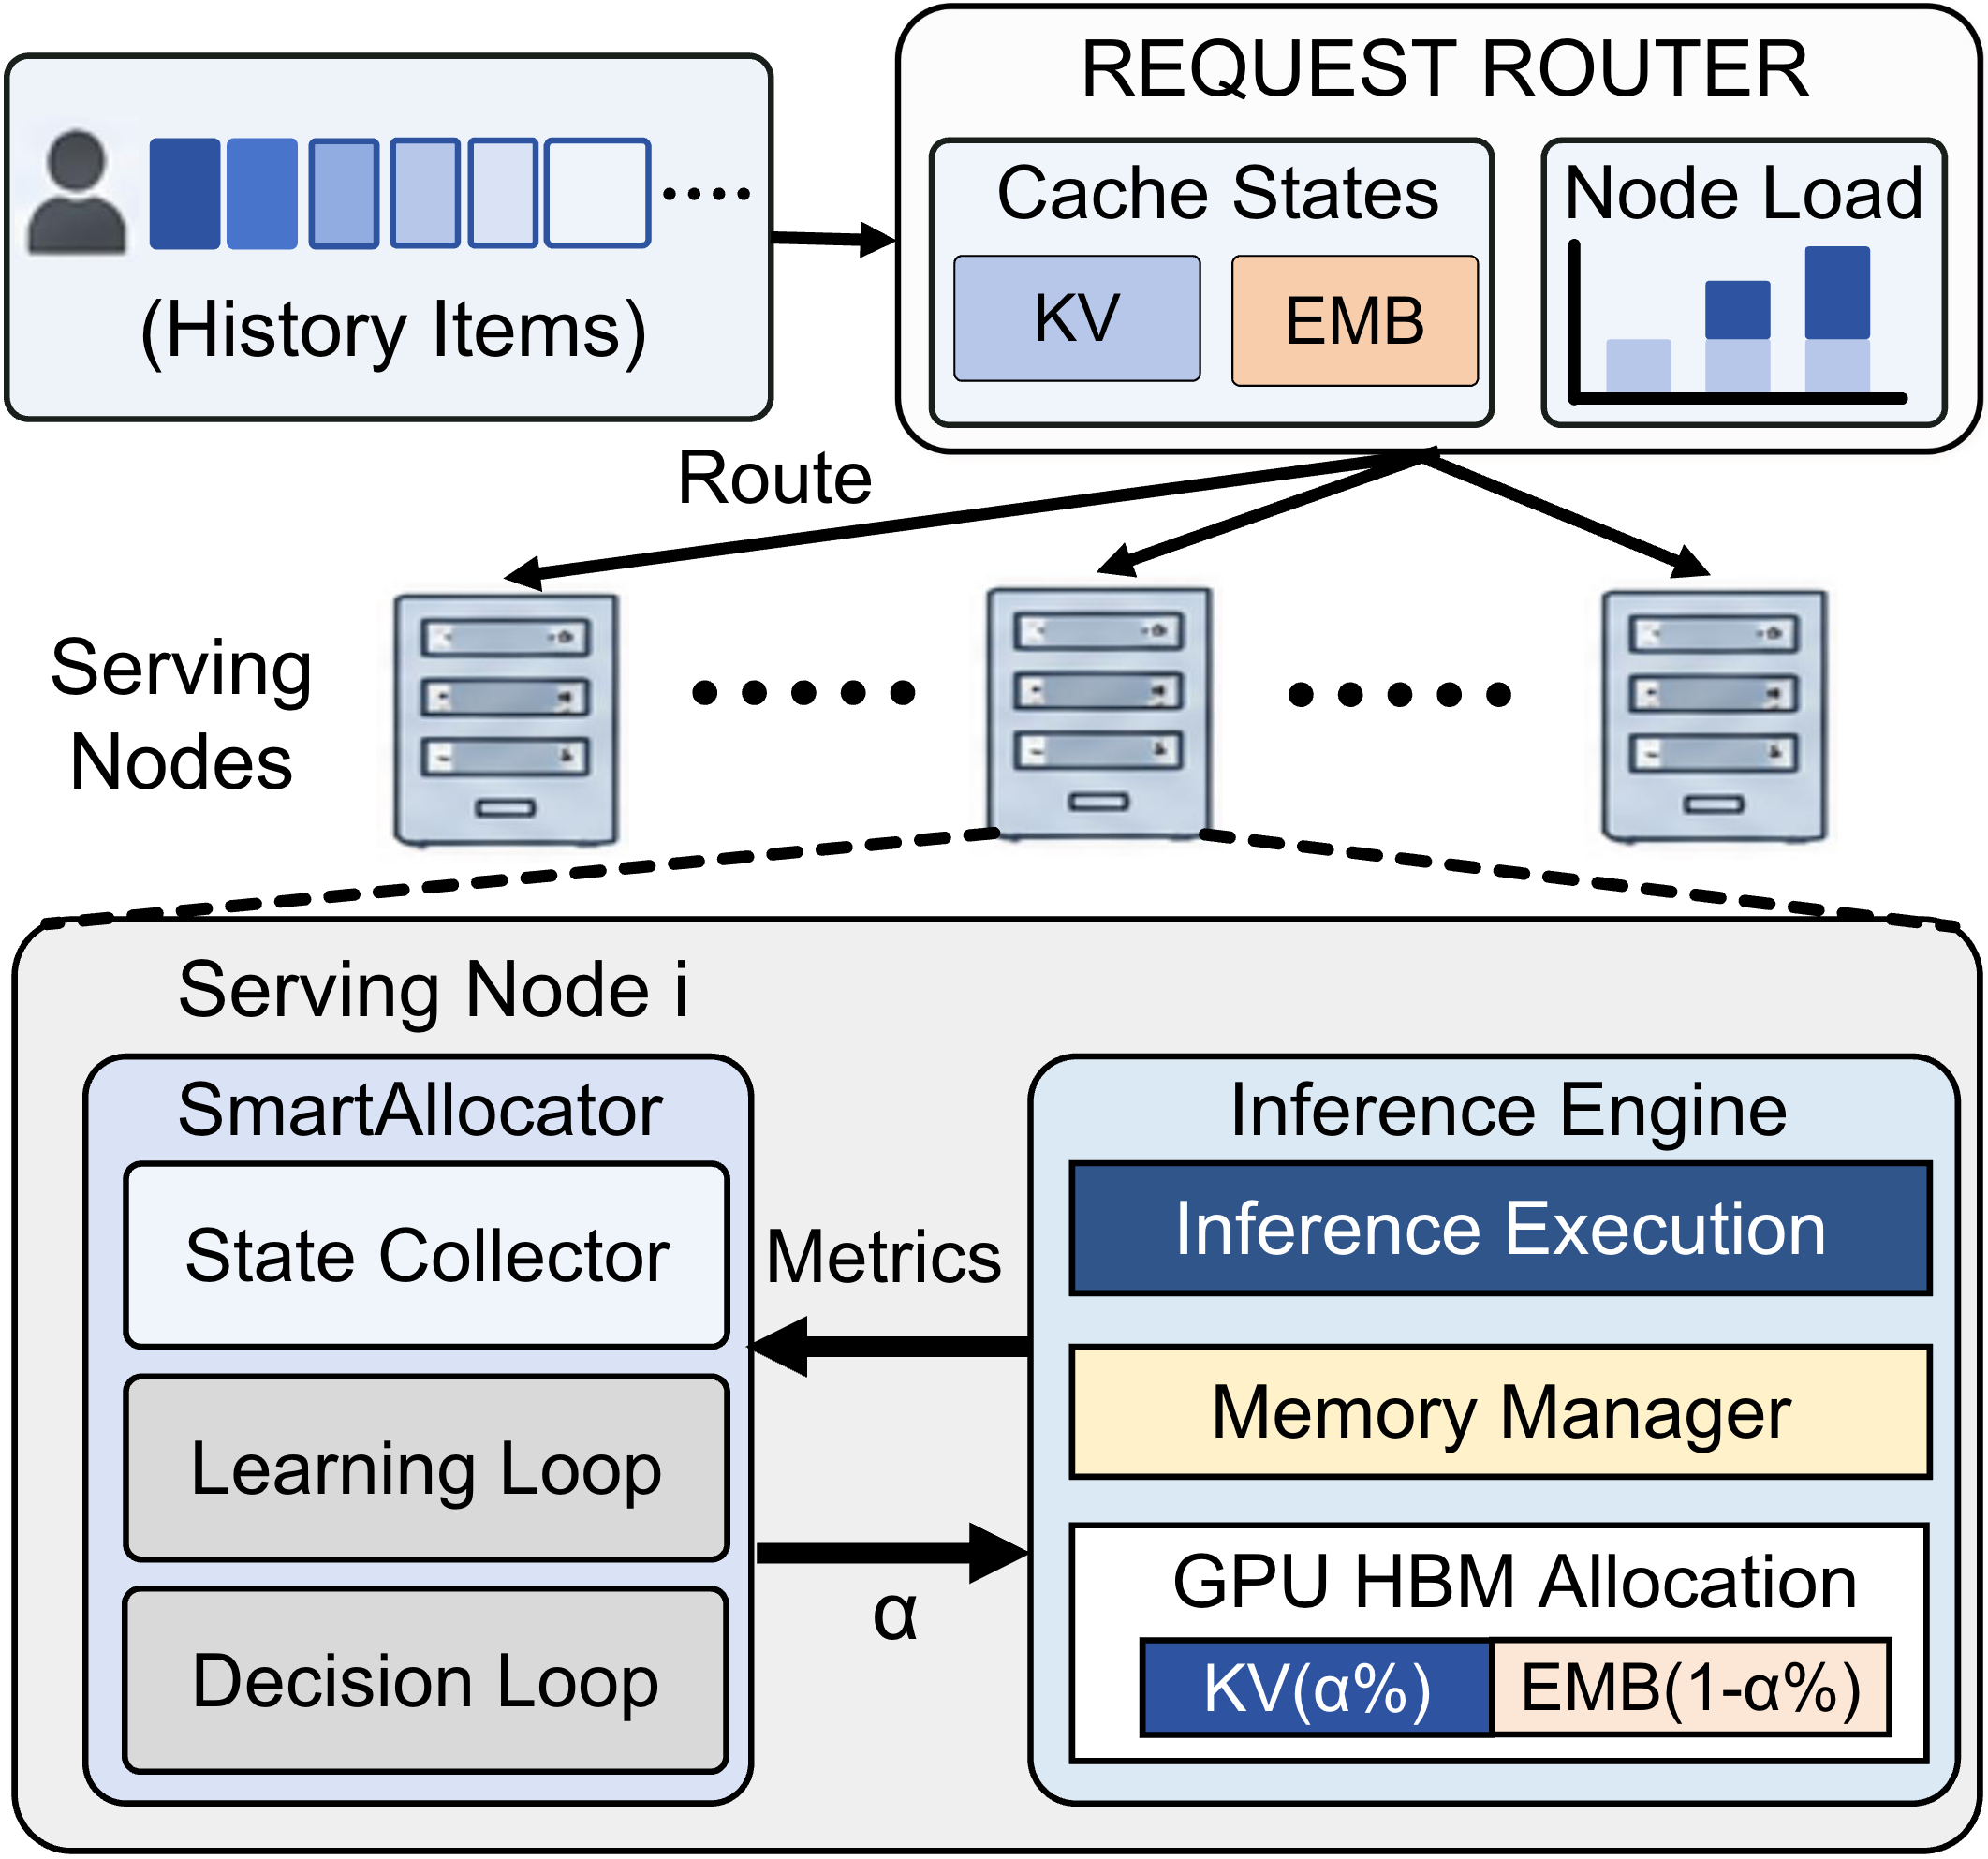
Generative Recommender inference faces a dual memory bottleneck absent in LLM serving: embedding hot caches and KV caches compete for the same limited GPU HBM, yet existing systems optimize them in isolation. We present RACER, which jointly reallocates HBM between the two caches at runtime and routes requests via a joint EMB–KV-aware scheduler, reducing P99 latency by 24–38% while maintaining ≥93.5% SLO satisfaction across production workload regimes.
When KV Meets Embeddings: Dynamic GPU Memory Allocation for Accelerating Generative Recommender Serving
Wenjun Yu, Amelie Chi Zhou, Shuguang Han — Alibaba (XianYu)
(SC 2026, CCF-A (19.2%)) International Conference for High Performance Computing, Networking, Storage, and Analysis
Generative Recommender inference faces a dual memory bottleneck absent in LLM serving: embedding hot caches and KV caches compete for the same limited GPU HBM, yet existing systems optimize them in isolation. We present RACER, which jointly reallocates HBM between the two caches at runtime and routes requests via a joint EMB–KV-aware scheduler, reducing P99 latency by 24–38% while maintaining ≥93.5% SLO satisfaction across production workload regimes.
Near-Zero-Overhead Freshness for Recommendation Systems via Inference-Side Model Updates
Wenjun Yu, Sitian Chen, Amelie Chi Zhou, Cheng Chen— ByteDance (Douyin)
(HPCA 2026, CCF-A (19.7%)) IEEE International Symposium on High-Performance Computer Architecture
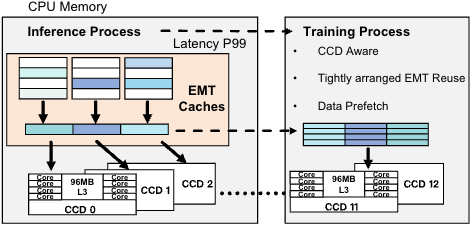
Updating online DLRMs is challenging due to their large model size. We address this by leveraging idle online CPU resources to perform continuous updates, thereby maintaining model freshness. Our approach employs dynamic rank adaptation and NUMA-aware resource scheduling to deliver these updates, significantly improving recommendation accuracy without impacting inference latency.
Near-Zero-Overhead Freshness for Recommendation Systems via Inference-Side Model Updates
Wenjun Yu, Sitian Chen, Amelie Chi Zhou, Cheng Chen— ByteDance (Douyin)
(HPCA 2026, CCF-A (19.7%)) IEEE International Symposium on High-Performance Computer Architecture
Updating online DLRMs is challenging due to their large model size. We address this by leveraging idle online CPU resources to perform continuous updates, thereby maintaining model freshness. Our approach employs dynamic rank adaptation and NUMA-aware resource scheduling to deliver these updates, significantly improving recommendation accuracy without impacting inference latency.